How to Estimate Your GPT-6 API Costs Before You Ship
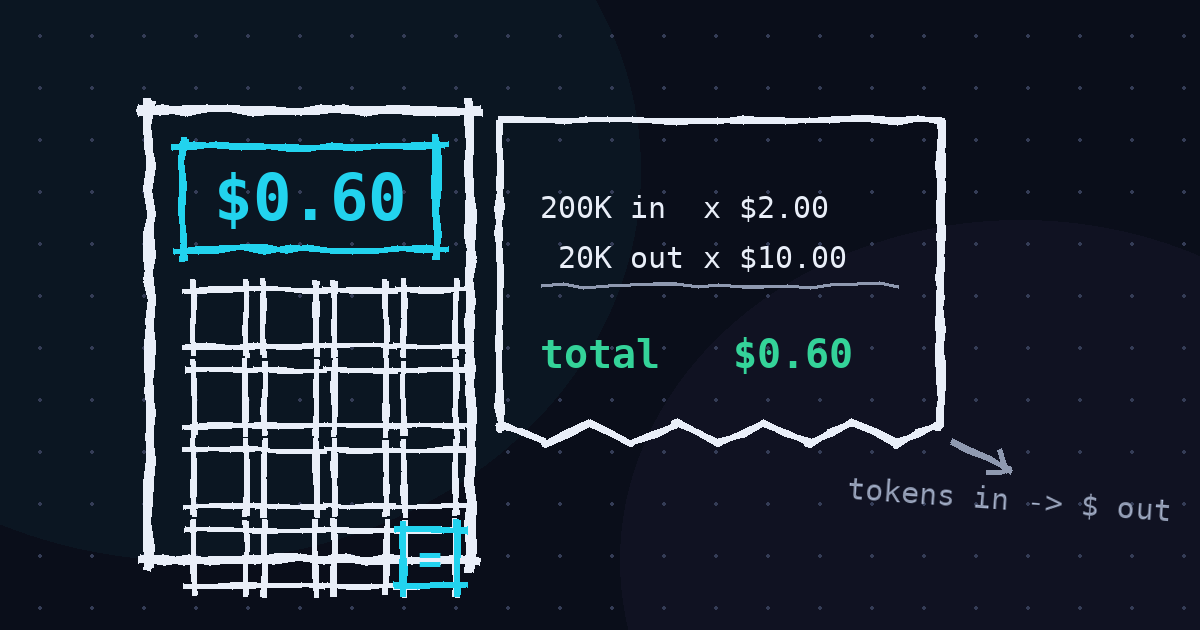
The formula for API cost is one line long. Getting the inputs right is where everybody faceplants. I've seen teams estimate $500 a month and land at $4,000 — not because the pricing is tricky (it's dead simple), but because the estimate forgot that conversation history grows, retries bill in full, and "a little dev traffic" is quietly doing 20% of production volume. So: the formula first, then the four gotchas that eat naive estimates alive.
Tokens 101: input vs output
Every API call bills two token streams. Input tokens are everything you send: the system prompt, conversation history, the user message, and any tool definitions. Output tokens are everything the model generates — including hidden reasoning tokens on reasoning models. Output is priced exactly 5× as much as input on every GPT-6 tier, which means output length dominates the bill far out of proportion to its token count.
Rule of thumb: 1,000 tokens ≈ 750 English words. A typical chat turn with history lands around 1,000–3,000 input tokens and 150–500 output tokens — measure yours from real logs, not from vibes.
The one formula you need
That's the whole thing. Take average tokens per request — from prototype logs or a pilot week — multiply by expected volume, apply your tier's per-million rates. Two refinements the calculator adds on top: the cached-input split (cached reads bill at 0.1× on Luna and Astra, 0.05× on GPT-6.1 Sol) and the 0.5× batch multiplier. But the formula above gets you within spitting distance.
Worked example: support chatbot
100,000 requests a month on GPT-6.1 Sol ($2.00 input / $10.00 output per 1M), averaging 2,000 input tokens and 300 output tokens per request:
- Input: 100,000 × 2,000 = 200M tokens → 200 × $2.00 = $400
- Output: 100,000 × 300 = 30M tokens → 30 × $10.00 = $300
- Total $700/month
Read that twice: output is 13% of the tokens and 43% of the money. That's the 5× output multiplier doing its quiet work — and it's why "make answers shorter" is the highest-leverage sentence in cost optimization. More tactics in our 10 cost-saving tips.
The four gotchas that eat naive estimates
- Reasoning tokens. On reasoning-heavy work, the model's internal chain-of-thought bills as output tokens — and a gnarly query can generate 5–10× more reasoning tokens than visible answer tokens. Your "short answers" aren't as short as they look.
- Retries and fallbacks. Every retry is a full re-bill. At 99% reliability on 100k requests, that's 1,000 extra calls you didn't model. Budget 1–3% overhead and move on.
- Conversation history growth. Multi-turn chats re-send history every turn. Model the average turn, not the first — it's usually 2–3× bigger, and the first turn is the cheapest lie your spreadsheet will ever tell you.
- Dev and eval traffic. Testing, evals, and staging routinely add 10–20% on top of production — and it's almost always on the expensive tier for no reason. Route dev and eval traffic to the cheapest tier; your future self says thanks.
Add a 20–30% buffer on top of the formula result. You'll land close to reality, which in this game counts as a win.
From spreadsheet to live tracking
Run the formula once for your launch forecast, then check actuals weekly in the OpenAI usage dashboard. If reality drifts more than 30% above forecast, something changed — and it's almost always prompt bloat or a missing max_tokens cap. Our free calculator runs the whole formula for you: requests, tokens, tier, done — input vs output broken out instantly.
Skip the spreadsheet — the calculator applies the formula with current GPT-6 pricing in seconds.
Open the calculator